
5 Hidden Challenges in Humanoid Robot Training Data and How to Solve Them
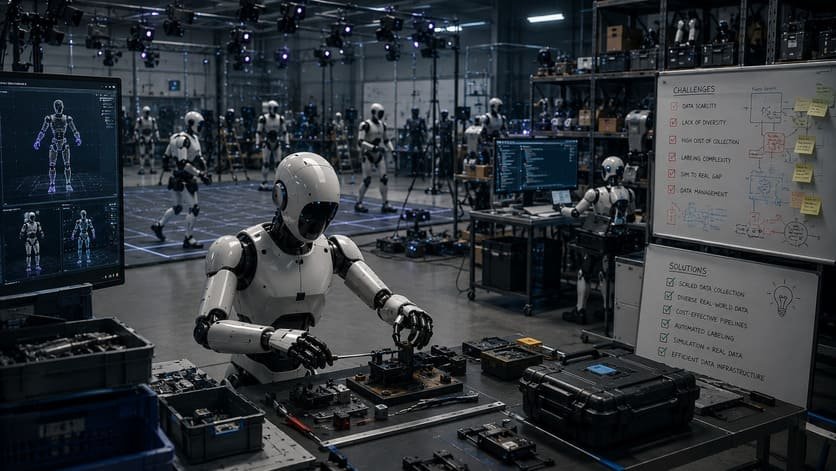
A recurring complaint in r/robotics threads, paraphrased, and repeated on roughly one buyer call a month: my retargeted dataset looks perfect in playback, and the robot still misses every grasp on hardware. The episodes play back fine. The file counts match the invoice. Training loss goes down. Then the policy ships to hardware and the robot’s foot slides on contact, or its fingers close 2 centimeters shy of the handle, and a corpus that cost six figures gets quietly deprecated in a Slack thread.
That engineer is not holding it wrong. Dataset quality is invisible at the file level; you cannot eyeball 4,000 hours. The defects that matter are statistical: a 40-millisecond sync drift here, a retargeting solver that clips a shoulder joint on 2 percent of frames there. Each one is small. Compounded across a training run, they put a ceiling on policy performance that no amount of additional data lifts.
Our thesis, argued from the QA floor: corpus quality is not a property you can see, it is a property you measure, and five specific, gateable defects account for most of the distance between data that trains and data that merely exists. We inspect every hour we deliver, and we have audited plenty of corpora we did not collect. This post covers those five defects, how each presents downstream, and the specific checks that catch them before training does.
Key Takeaways – The five hidden challenges: retargeting error, hand-data scarcity, synchronization drift, locomotion-manipulation imbalance, and unmeasured sim-to-real gaps. – Each is invisible at the episode level and expensive at the policy level; all five are catchable with automated per-episode gates. – Our operating thresholds: joint-limit violations under 0.5 percent of frames, end-effector error under 2 cm, sync within one frame at 30 fps. – Rejection rates are a health signal. Pipelines reporting zero rejected episodes are not measuring.
Challenge 1: Retargeting Error That Passes the Eye Test
Retargeting error is the geometric and dynamic distortion introduced when human motion is mapped onto a humanoid’s different link lengths, joint limits, and mass distribution. It is the tax on every dollar saved by capturing humans instead of robots, and it hides well: a retargeted episode can look natural in playback while violating the robot’s shoulder limits on thousands of frames.
The downstream symptom is a policy that learns kinematically impossible targets and saturates actuators chasing them. Research systems that made human-to-humanoid transfer work, H2O (arxiv.org/abs/2403.04436), OmniH2O (arxiv.org/abs/2406.08858), HumanPlus (arxiv.org/abs/2406.10454), all invest heavily in exactly this mapping.
The fix: automated per-episode gates, not spot checks. Ours: joint-limit violation rate below 0.5 percent of frames, post-retargeting end-effector error under 2 cm against reconstructed hand pose, and foot-skate detection flagging stance-foot translation above 1 cm per frame. On typical egocentric batches, first-pass rejection runs 10 to 20 percent. That number should exist for your corpus, whoever collects it.
Challenge 2: The Hand Data Gap
Hand data scarcity is the systematic under-representation of finger-level detail in humanoid corpora, caused by occlusion, resolution limits, and capture hardware that treats hands as an afterthought. Bodies are easy; 21-plus joints per hand moving at high speed behind the very object being manipulated are not. Mocap suits barely see fingers. Egocentric cameras lose them at the moment of grasp, which is the moment that matters.
The symptom: policies that reach perfectly and grasp badly. Manipulation is where humanoid economics live, so this is the most expensive gap in the stack.
The fix: treat hands as a first-class capture target. On our rigs that means stereo egocentric cameras framed for the workspace rather than the horizon, hand-tracking gloves paired with mocap suits on manipulation tasks, and a visibility quota: reconstructed hand pose must be valid in at least 85 percent of frames during manipulation segments or the episode is flagged. Datasets like EgoExo4D (arxiv.org/abs/2311.18259) added synchronized exocentric views partly to recover exactly this occluded detail; a second viewpoint is cheap insurance.
Challenge 3: Synchronization Drift Across Streams
Synchronization drift is the gradual misalignment of timestamps across a rig’s sensors, so that by minute 40 the video frame no longer matches the joint state it is paired with. Independent clocks drift; USB buffers hiccup; a 30 fps stream needs alignment within roughly 33 milliseconds, one frame, for observation-action pairs to stay honest.
The symptom is subtle and brutal: the model learns actions offset from their true observations, which reads as unexplained clumsiness after transfer. No amount of data fixes labels that are wrong in time.
The fix: hardware sync where possible (shared trigger or PTP), and measured sync everywhere. We inject clap-style sync events at episode boundaries and verify cross-stream alignment within one frame at 30 fps per episode; drift beyond tolerance rejects the episode automatically. Ask any vendor a simple question: “what is your measured, not assumed, sync tolerance?” The pause tells you a lot.
Challenge 4: Locomotion-Manipulation Imbalance
Locomotion-manipulation imbalance is a corpus skewed toward whole-body motion because walking data is easy to produce, while the manipulation data that deployments actually monetize stays thin. Sim generates locomotion nearly free in Isaac Lab; mocap suits capture gait beautifully. Meanwhile every hour of contact-rich manipulation must be earned with hands, objects, and QA.
The symptom shows up at the business layer: a robot that navigates the warehouse confidently and cannot pack a tote. Platforms like Agility’s Digit earn their keep with what happens between the walking.
The fix: budget by task value, not capture convenience. Set explicit corpus ratios in the data plan, audit them monthly, and let sim carry locomotion so real-capture dollars concentrate on manipulation. Our worked budget split is in the comparison post and the pillar guide.
Challenge 5: The Unmeasured Sim-to-Real Gap
The sim-to-real gap is the performance loss a policy suffers moving from simulated physics to real hardware, and the hidden challenge is not that it exists but that most teams never measure it per task. Domain randomization in Isaac Lab and MuJoCo narrows the gap for locomotion. For fingertip friction, deformables, and cloth, it remains wide, and a corpus plan that assumes sim covers manipulation inherits that error silently.
The fix: a standing transfer benchmark. Hold out a fixed suite of real-hardware tasks, evaluate every sim-trained checkpoint on it, and track the sim-real delta per task family over time. Where the delta stays wide, that is precisely where real capture budget belongs. This turns the sim-vs-real argument from opinion into a number your team can budget against.
How the Five Challenges Compound
Corpus defects multiply rather than add, because each one independently reduces the fraction of episodes carrying clean learning signal. Suppose 3 percent of frames carry retargeting artifacts, 5 percent of manipulation segments lack valid hand pose, and sync drifts past a frame on 4 percent of long episodes. No single number alarms anyone. Together, and correlated with exactly the long, contact-rich episodes that matter most, they can quietly degrade a meaningful slice of your most valuable data.
This is why we argue for gate-based acceptance rather than sampling-based review. A human reviewer watching 1 percent of episodes will approve a corpus with all five defects present. An automated gate suite run on 100 percent of episodes will not. The compute cost of full-coverage QA is trivial next to a single wasted training run on a large VLA, and it converts data quality from a belief into a report.
The Checklist
Before accepting any humanoid data delivery, confirm:
- ☐ Per-episode retargeting gates with published thresholds and rejection stats
- ☐ Hand-pose validity quota on manipulation segments (ours: 85 percent of frames)
- ☐ Measured synchronization tolerance, within one frame at capture fps
- ☐ Corpus-level locomotion/manipulation ratio matching your task economics
- ☐ A real-hardware transfer benchmark for anything sim-trained
- ☐ Re-collection policy for rejected batches, in writing
The full vendor-evaluation version of this list is the RFP Scorecard inside The Complete Guide to Humanoid Robot Training Data.
Next Step
Run the six-point checklist against your current corpus or your next vendor delivery. If any box is unchecked, the RFP Scorecard in The Complete Guide to Humanoid Robot Training Data gives you the exact questions to ask, and we are happy to be asked them first.
Frequently Asked Questions
What is the most common defect in humanoid robot training data?
In our audits, retargeting error: human motion mapped to the robot with joint-limit violations, end-effector drift, or foot skate that playback hides. It is caught with automated per-episode geometric gates, not visual review.
How accurate does sensor synchronization need to be?
Within one frame of the primary camera stream, roughly 33 milliseconds at 30 fps. Beyond that, observation-action pairs mislabel each other and policy quality degrades in ways more data cannot repair.
Why is hand data so hard to collect for humanoids?
Fingers are occluded by the object being manipulated, move fast, and pack 21-plus joints into a small, self-occluding volume. Reliable coverage requires purpose-framed stereo capture, glove tracking, or a second synchronized viewpoint.
Can domain randomization close the sim-to-real gap for manipulation?
Only partially. It works well for locomotion and rigid-body interaction, but fingertip friction, deformable objects, and cloth still transfer poorly, so contact-rich manipulation data should come from real capture.
What rejection rate is normal for retargeted human data?
We see 10 to 20 percent first-pass rejection on egocentric batches under our gates. A reported rate near zero usually means the gates are missing, not that the data is perfect.
Sainath Gupta
Sainath Gupta is the visionary leader of DexSet, a company dedicated to building the foundational data layer for the robotics revolution. Sainath recognized early on that the primary bottleneck for physical AI wasn't hardware or model architecture, but the lack of high-quality, scalable training data.
At DexSet, he has pioneered a "manufacturing-first" approach to data collection. This includes the development of transparent cost-per-hour benchmarks and the scaling of global networks for egocentric and teleoperation capture. Sainath is a vocal advocate for the industry’s shift toward treating human experience as the primary pretraining substrate for robots. His leadership at DexSet is focused on one goal: providing the millions of hours of high-fidelity data required to bring humanoid robots out of the lab and into the real world.