
How to Tell If Data Is Your Robot’s Real Bottleneck
Key takeaways
- Most robotics teams blame the model when the real constraint is the data.
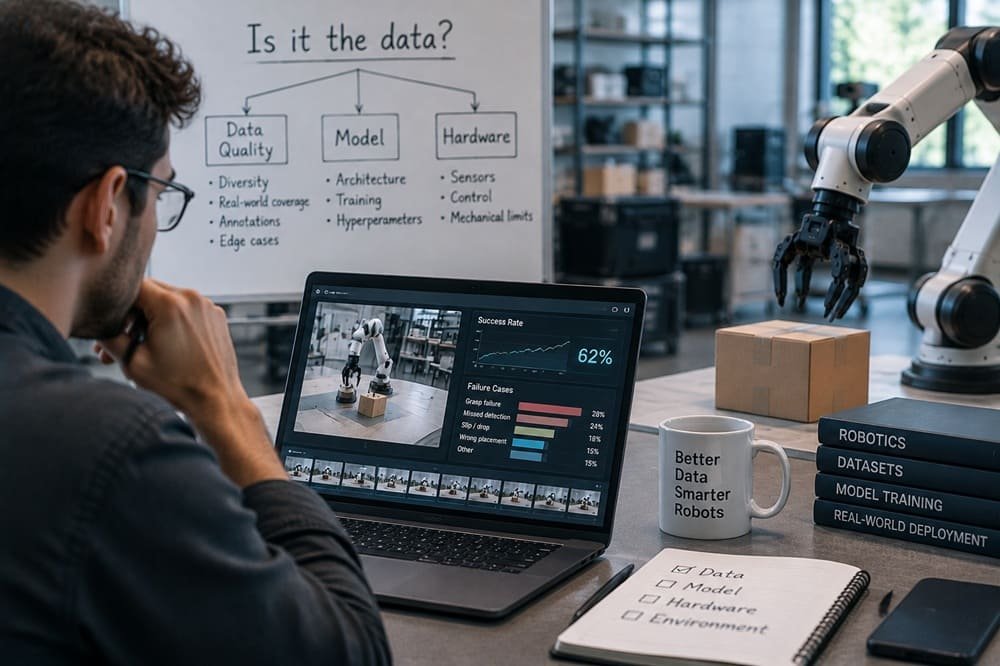
- The tell is where failures cluster: on specific tasks, objects, or conditions your dataset under-covers.
- A leak-free held-out gap, a coverage score, and a targeted data-add experiment will confirm it in about 30 minutes of analysis plus a re-train.
Your policy nails the demo and falls apart in the field. Before you rearchitect the model, run this diagnostic — because in 2026 the robot data bottleneck, not compute or architecture, is what blocks most deployments. Analysts describe data quality as the primary barrier to scaling robots to production, and NVIDIA’s dexterity scaling law shows how much targeted real-world data moves task completion. Here’s how to know if that’s your problem.
Step 1 — Map where failures cluster
Log failures by task, object, and environment. If they scatter randomly, suspect the model or reward. If they cluster — the robot fails on transparent objects, on cluttered shelves, in low light, on the last step of a sequence — that is a coverage gap, and coverage gaps are data problems. See our pillar on real-world training data for why context-specific failure is the signature of a data issue.
Step 2 — Compare train vs held-out performance
Evaluate on the conditions you trained on, then on a held-out set captured in separate sessions with documented provenance. A small gap means your model generalizes; a large gap means it memorized a distribution it can’t leave. If your eval set leaked from training, you won’t even see the gap — fix that first.
Step 3 — Score your dataset's coverage
List the variation axes that matter for the task — object types, poses, lighting, clutter, operators, environments, failure modes — and measure how many your dataset actually covers. Most teams discover they have thousands of near-identical episodes and near-zero coverage of the cases that break the policy. This is why coverage beats volume.
Step 4 — Audit episode and label quality
Pull a random sample of episodes and inspect for dropped timestamps and sensor desync, label noise on action and outcome tags, and low-quality teleoperation that the model may be imitating. Quality problems masquerade as model problems: a policy trained on sloppy demonstrations learns sloppy behavior.
Step 5 — Run a targeted data-add experiment
Capture or source real-world data specifically for the failing variation, add it, and re-train. If the failures resolve, you have your answer: data was the bottleneck, and the fix is targeted capture, not a bigger network.
Step 6 — Decide: collect, clean, or change the model
- Targeted data fixed it → invest in capture and coverage; stand up a data flywheel so new edge cases keep flowing in.
- Cleaning fixed it → your pipeline needs QA gates, not more data.
- Neither helped → now it’s worth revisiting architecture, action representation, or reward.
The short version
If failures cluster on specific conditions, your held-out gap is large, and your coverage score is thin, data is your bottleneck — and it’s the most fixable one. Start by capturing the exact variation you’re missing.
Next Step
dexset can score your current dataset’s coverage and pinpoint the variation your policy is missing — before you spend on scale.
Sainath Gupta
Sainath Gupta is the visionary leader of DexSet, a company dedicated to building the foundational data layer for the robotics revolution. Sainath recognized early on that the primary bottleneck for physical AI wasn't hardware or model architecture, but the lack of high-quality, scalable training data.
At DexSet, he has pioneered a "manufacturing-first" approach to data collection. This includes the development of transparent cost-per-hour benchmarks and the scaling of global networks for egocentric and teleoperation capture. Sainath is a vocal advocate for the industry’s shift toward treating human experience as the primary pretraining substrate for robots. His leadership at DexSet is focused on one goal: providing the millions of hours of high-fidelity data required to bring humanoid robots out of the lab and into the real world.